Research
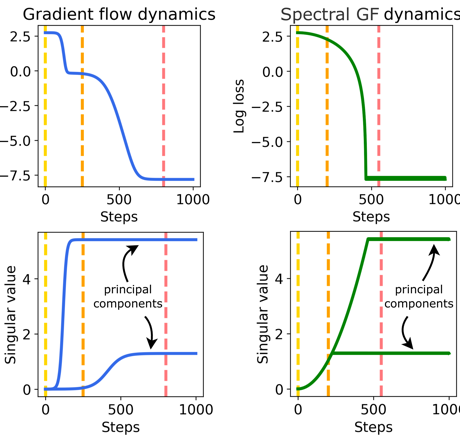
To Use or not to Use Muon: How Simplicity Bias in Optimizers Matters

Softmax ≥ Linear: Transformers may learn to classify in-context by kernel gradient descent

Strategy coopetition explains the emergence and transience of in-context learning